
vLLM-Omni
High-performance serving framework for omni-modal models.
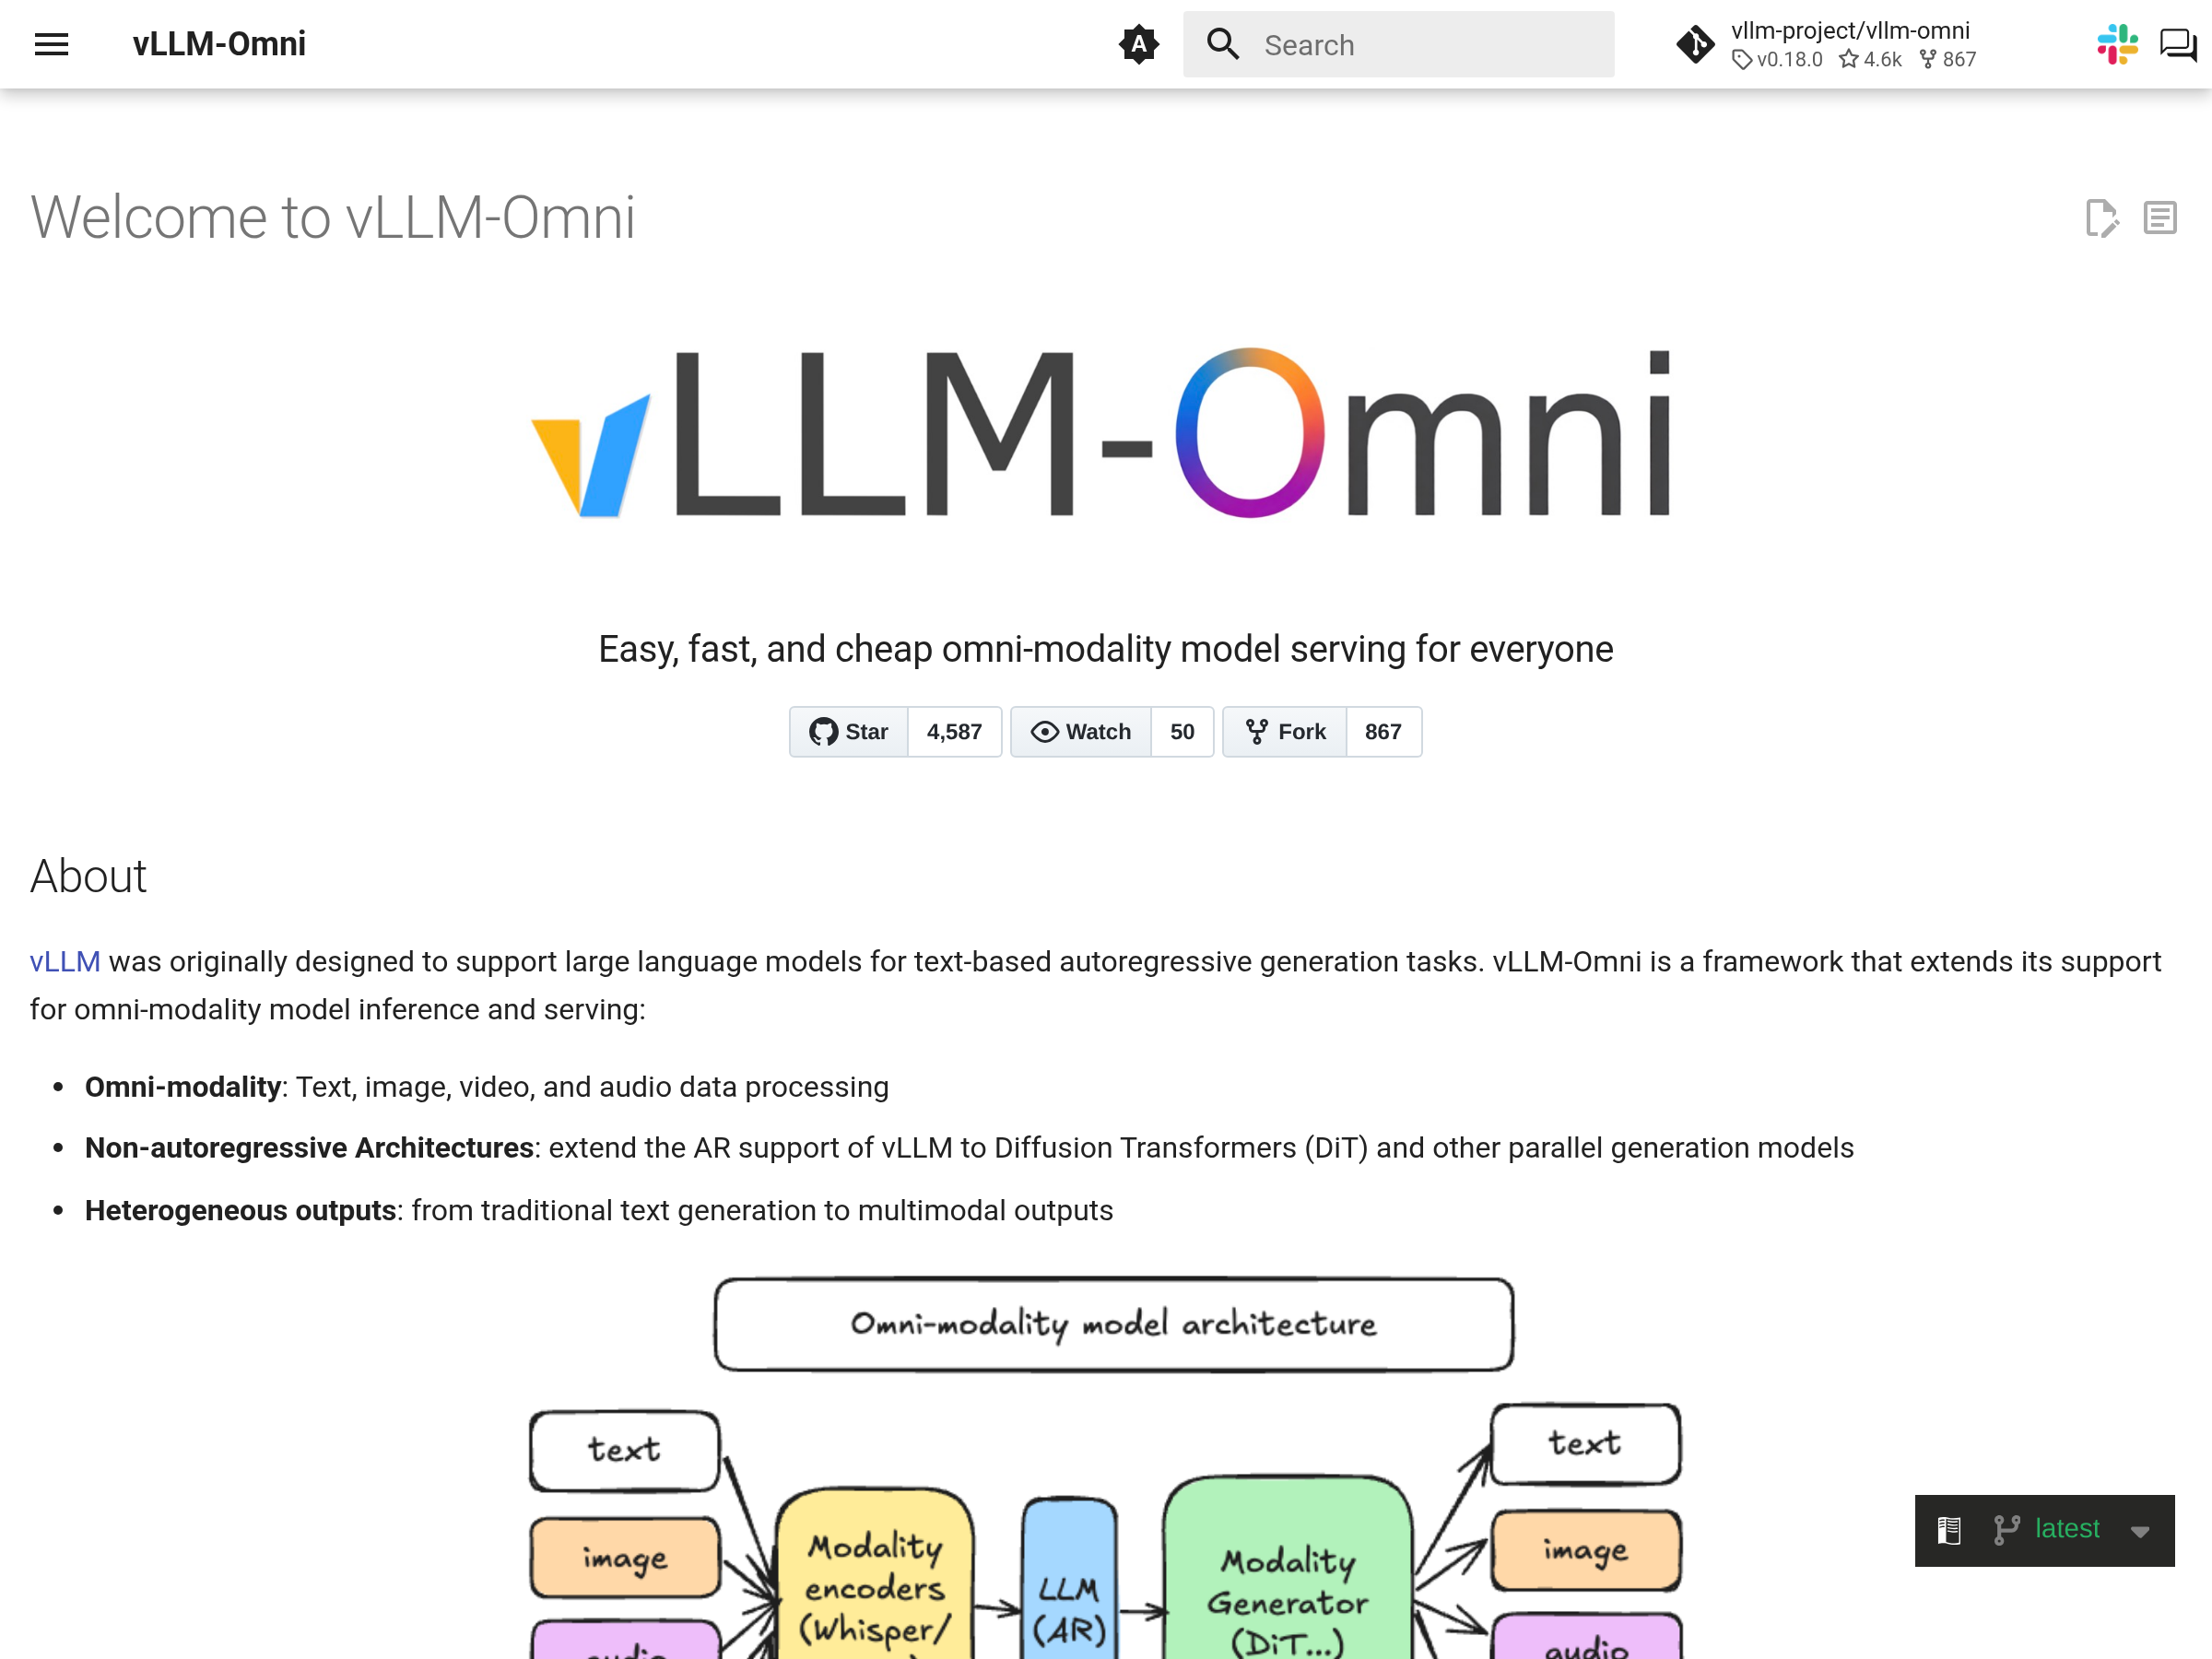
Open-source high-performance serving framework for multimodal generative models, covering unified production inference for text, image, audio, and video workloads.
Recent stories
2 linked stories
releaseSECONDARY2026-09-20
Qwen releases Qwen-Image-2.1 with open weights
Qwen-Image-2.1 is a 7B model that combines image generation and editing, including native RGBA output and support for up to 10 reference images. It has day-one support in ComfyUI, Diffusers, vLLM-Omni, and Ostris, but its license is non-com
releaseSECONDARY2026-08-02
MiniMax releases H3 open weights with day-zero vLLM-Omni support
MiniMax released H3 weights on Hugging Face for text-to-video, image-to-video, reference-to-video, and editing workflows. vLLM-Omni, ComfyUI, SGLang Diffusion, and fal added support at launch.