
xAI launches Grok 4.7 at Grok 4.6’s price
xAI says Grok 4.7 improves on 4.6 without changing price or speed. It is available in Grok Build, Cursor, and the API, with higher scores on several agent benchmarks.
TL;DR
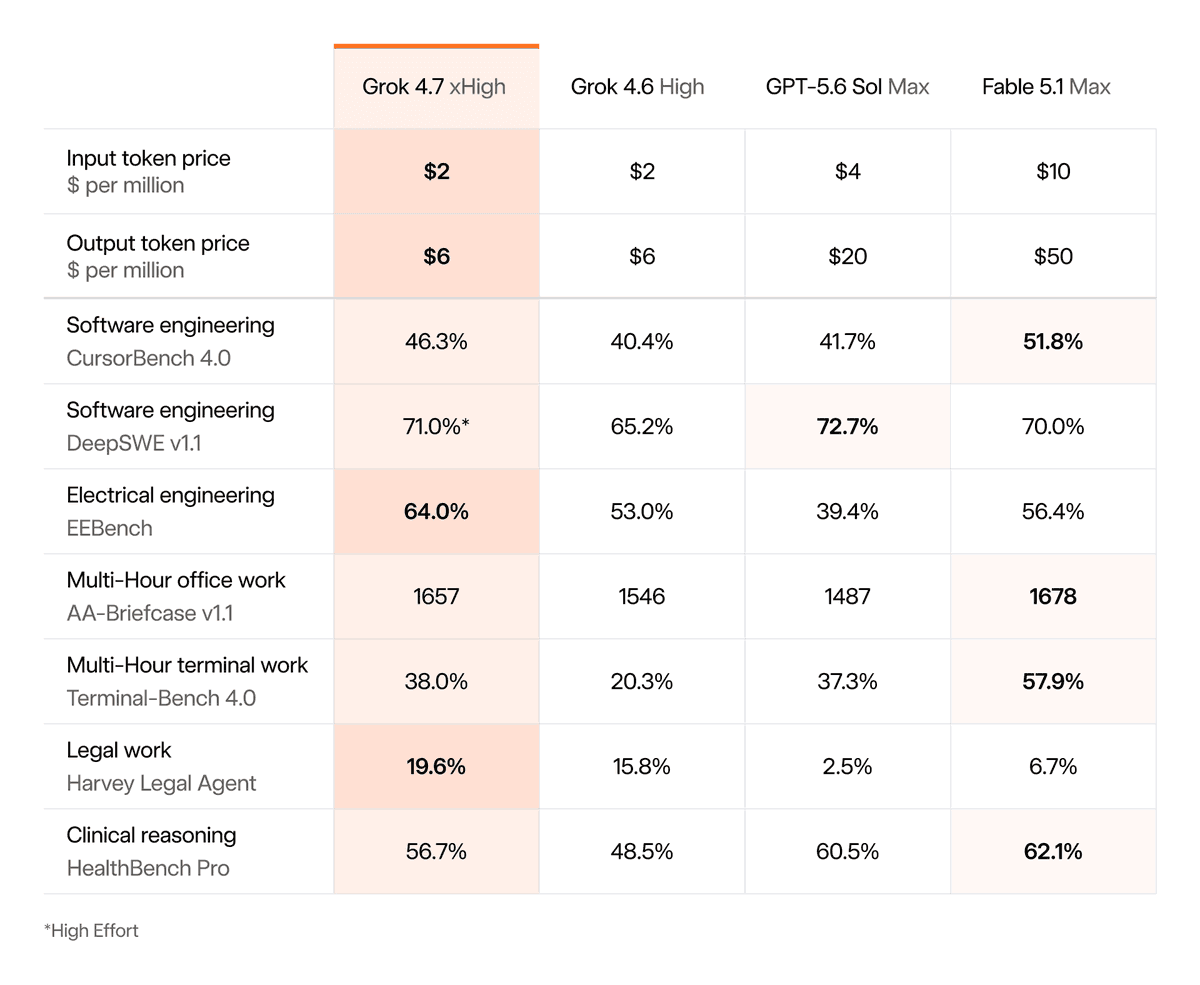
- Grok 4.7 retains Grok 4.6’s $2-per-million input and $6-per-million output list prices, according to minchoi's score summary.
- Terminal-Bench 4.0 rose from 20.3% to 38.0%, a +17.7-point first-party result reported in ericzakariasson's model-card post.
- Independent testing puts the Artificial Analysis Intelligence Index at 44 to 46, while minchoi's score summary records xAI’s 40.4% to 46.3% CursorBench comparison.
- Cursor, Grok Build and the Grok API have day-one access, as SpaceXAI's availability post confirms.
The official launch post describes a larger base model and a longer reinforcement-learning run aimed at multi-hour work. Artificial Analysis’s evaluation found the biggest external gains in agentic knowledge work, alongside 81,000 output tokens per Intelligence Index task at xhigh effort.
What shipped
- Cursor, Grok Build and the Grok API are live now, per SpaceXAI's availability post.
- API list prices remain $2 per million input tokens and $6 per million output tokens, as minchoi's score summary notes and the official launch post confirms.
- A faster variant doubles output speed and price, while xAI says the standard model keeps Grok 4.6’s speed, according to SpaceXAI's launch post.
Benchmarks that moved
First-party
- CursorBench 4.0: 40.4% → 46.3%, +5.9 points, in minchoi's score summary.
- Terminal-Bench 4.0: 20.3% → 38.0%, +17.7 points, per ericzakariasson's model-card post.
- HealthBench Professional: 48.5% → 56.7%, +8.2 points, per ericzakariasson's model-card post.
- Harvey Legal Agent Benchmark: 15.8% → 19.6%, +3.8 points, per ericzakariasson's model-card post.
Third-party evaluators
- Artificial Analysis Intelligence Index: 44 → 46, +2 points, in Artificial Analysis’s evaluation at xhigh effort.
- Artificial Analysis Coding Agent Index with Grok Build: 47 → 56, +9 points, in Artificial Analysis’s evaluation.
- AA-Briefcase, a long-horizon professional-work benchmark: 1,546 Elo → 1,657 Elo, +111 Elo, in Artificial Analysis’s evaluation.
Customer-reported
Cursor’s launch-day discussion asks users for long-session results rather than publishing a customer score.
Where it regressed
Independent evaluation found uneven movement outside agentic work. Artificial Analysis’s evaluation reports a 3.7-point decline on AA-LCR and a 1.1-point decline on AutomationBench-AA.
- AA-Omniscience accuracy: 48% → 47%, -1 point, in Artificial Analysis’s evaluation, even as its hallucination rate fell from 34% to 29%.
- Output use per Intelligence Index task: 36,000 → 81,000 tokens, +125%, in Artificial Analysis’s evaluation. Those figures compare 4.6 at high effort with 4.7 at xhigh.
- CursorBench 4.0: Fable 5.1’s 51.8% → Grok 4.7’s 46.3%, -5.5 points, in xAI’s launch table.
Under the hood
- Base and training: xAI describes a new, larger base model plus a longer reinforcement-learning run on a harder mixture weighted toward tasks that take many hours. The launch post gives no parameter count.
- Agent harness: training to natively understand the Grok Bot harness is meant to improve conversational work and general knowledge tasks, according to SpaceXAI's model description.
- Context: the window remains 500,000 tokens, according to Artificial Analysis’s evaluation.
- Safety: xAI says 4.7 uses an entirely new safeguard stack, allowed 3.3% of risky dual-use cyber prompts through on its HackerBench v0.3 test, and topped its cited LatchBio biosafety benchmark at 62.4%.
Vibe Check
minchoi’s examples roundup collects showcase posts rather than a standardized creative evaluation, but the early material is unusually centered on interactive output.
- SpaceXAI’s city-game comparison puts open-world city builds from 4.7 and 4.6 side by side.
- A Blender scene made with “almost no direction” appears in minchoi's Blender example, while minchoi's robot-arm animation attributes a robot-arm animation to HTML generated by 4.7.
- A complete playable game from a one-line prompt is the claim in minchoi's one-line game example.
- minchoi’s 70-hour claim describes an autonomous run on one goal lasting more than 70 hours.
- A Three.js cloth simulation appears in minchoi's cloth-simulation clip.