
GPT-6.2 Astra scores 100% on ARC-AGI-3 with a provider adapter
ARC Prize verified GPT-6.2 Astra at 100% on ARC-AGI-3 with a provider adapter, versus 70.3% with its standard harness. Sol reached 98.2% with the adapter at 64% lower cost than Astra.
TL;DR
- Astra reached a verified 100% on ARC-AGI-3 with a provider adapter at $4.1K, versus 70.3% at $24.2K with the Standard harness, according to ARC Prize.
- Sol finished 1.8 percentage points behind Astra at 64% lower cost in ARC Prize's comparison, reaching 98.2% for about $1.5K.
- Reasoning-token savings depend on effort: ARC Prize measured 51% fewer tokens on ARC-AGI-2 from low through xhigh, but 12% more at max, compared with GPT-6 Astra.
The most interesting switch in the benchmark runner is manual_rolling versus continuous_conversation. In Astra's public-game results, its max-effort score on G50T jumps from 0.4% with the Standard harness to 100% with the adapter.
ARC-AGI scores and costs
ARC Prize's reported scores and costs compare each harness's best result, rather than holding reasoning effort constant:
| Model | Standard harness | Provider Adapter | Score difference |
| --- | --- | --- | --- |
| Astra | 70.3%, $24.2K | 100.0%, $4.1K | +29.7 points |
| Sol | 54.9%, $5.5K | 98.2%, $1.5K | +43.3 points |
Costs here are totals for the ARC-AGI-3 evaluations, not per-task prices.
Earlier benchmarks, score and cost per task
| Benchmark | Astra | Sol |
| --- | --- | --- |
| ARC-AGI-1 | 98.5%, $0.17 | 97.5%, $0.06 |
| ARC-AGI-2 | 95.8%, $0.50 | 85.8%, $0.13 |
The perfect score prompted koltregaskes to ask, “When is ARC 4?”
Provider Adapter
ARC-AGI-3 games span many model calls. The official runner defines two ways to carry information between actions:
- Standard,
manual_rolling: Provider-neutral text history, with useful discoveries preserved in visible notes chosen by the model. - Provider Adapter,
continuous_conversation: Native conversation and reasoning state, with native compaction when available or a domain-neutral harness summary otherwise.
Both use the same games, actions, limits and scoring. ARC Prize reports them separately because the Standard harness supports controlled cross-provider comparisons, while the adapter measures performance with provider-native context management.
The terminology drew a direct request for implementation detail:
Reasoning effort labels
The detailed results table differs from the announcement's effort labels on both winning runs:
- Astra: 100% at xhigh, versus 99.8% at max. The announcement described the perfect score as a max-effort result.
- Sol: 98.2% at max, versus 90.1% at high. The announcement described its best result as high effort.
At matched xhigh effort, Astra scores 56.5% with the Standard harness and 100% with the adapter, a 43.5-point difference.
Reasoning tokens and actions
ARC Prize compared GPT-6.2 Astra with its predecessor, GPT-6 Astra, across distinct public and semi-private evaluations:
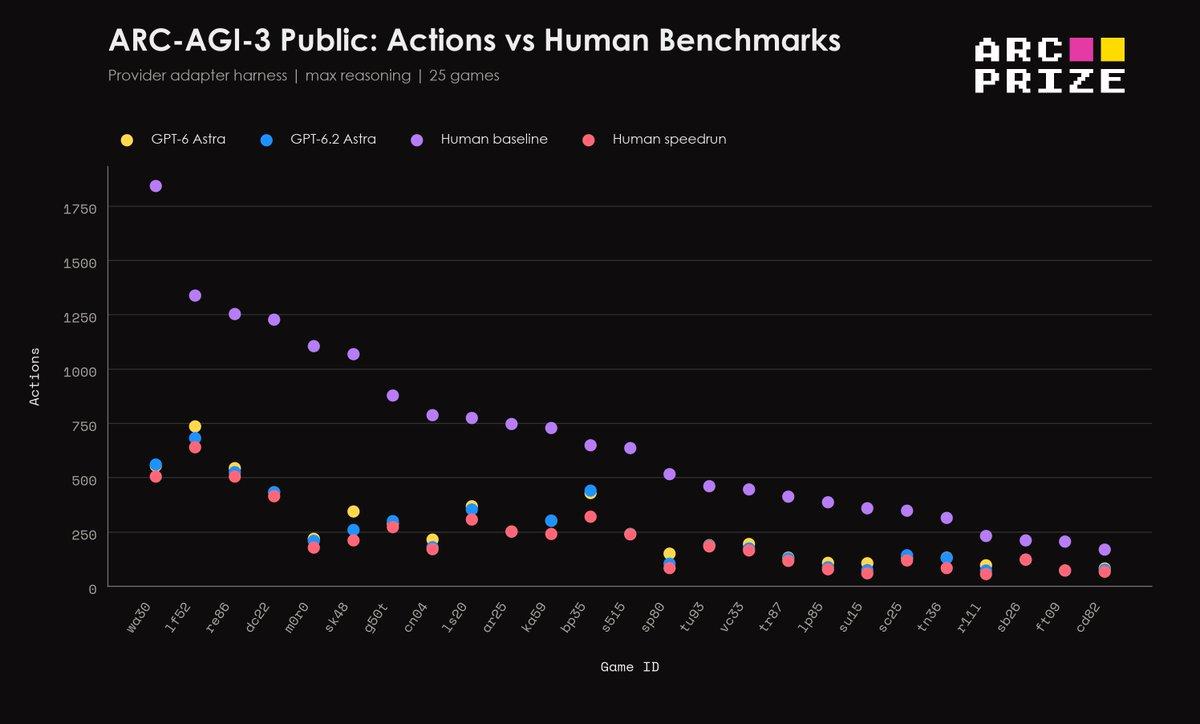
- Public ARC-AGI-3 actions: At max effort with the adapter, Astra used 5.2% fewer actions than its predecessor and 64.1% fewer than the human baseline across 25 games, according to ARC Prize's action counts.
- Semi-private ARC-AGI-2 reasoning: Token use fell 51% across low through xhigh, but rose 12% at max in ARC Prize's measurements.
- Semi-private ARC-AGI-3 first actions: First-action reasoning tokens fell 53% across low through max with the adapter in ARC Prize's comparison.
Astra also invoked reasoning on a smaller share of actions at every effort level in the semi-private ARC-AGI-3 adapter runs:
Public runs and incomplete coverage
ARC Prize published four resources for inspecting the evaluations:
Sol's individual results page flags partial coverage: two v1/v2 tasks and eight v3 games remain incomplete across the published evaluations. Scores use full-dataset denominators, while costs include only recorded usage.