
NVIDIA releases Nemotron 3.5 models for document-image search
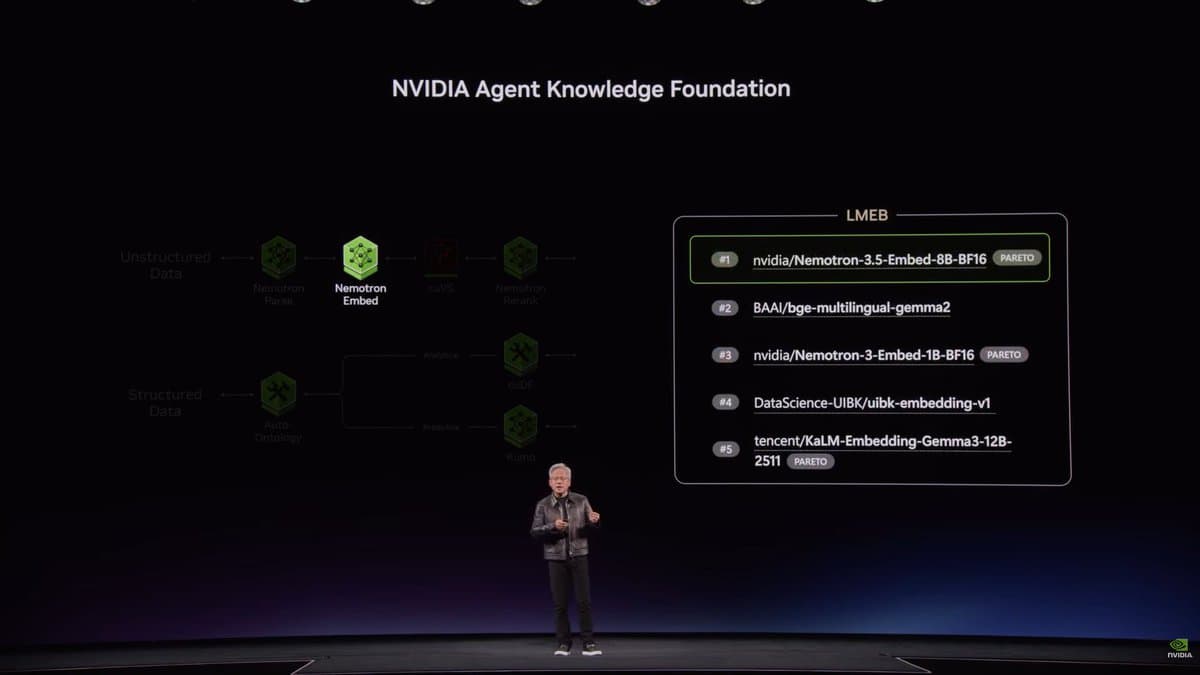
NVIDIA released Nemotron 3.5 Embed and Rerank models with document-image support through Sentence Transformers. NVIDIA reports reranking raises its ViDoRe v3 image-and-text result from 58.82 to 67.56 nDCG@10.
TL;DR
- Document-image retrieval now works through Sentence Transformers: tomaarsen's walkthrough covers NVIDIA's Nemotron 3.5 Embed 1B, Embed 8B and Rerank 8B.
- Existing Nemotron 3 text vectors can carry over to the corresponding 3.5 embedding models, according to tomaarsen's explanation of the training setup.
- Reranking lifts NVIDIA's ViDoRe v3 image-and-text result from 58.82 to 67.56 nDCG@10, +8.74 points, in the reported comparison.
The 1B model card lists 1.55B actual parameters and a 32,768-token context. NVIDIA also reports 27.1% higher document throughput for its NVFP4 variant on GB200, retaining 99.85% of BF16 retrieval accuracy on ViDoRe v3 with image-and-text inputs.
Single-vector page search
Both embedding models produce one vector per input for a conventional vector index, as tomaarsen explains. Queries are text-only; documents can be text, page images, or paired image-and-text inputs.
The 1B model card documents the interface and vector format:
encode_query()applies the saved query prefix.encode_document()accepts text strings or dictionaries containingimage,text, or both.- Mean pooling and L2 normalization produce one 2,048-dimensional vector per input.
- Vectors can be truncated to dimensions such as 1,024 or 512, with L2 normalization applied again after truncation.
Text-vector compatibility
NVIDIA froze the language component throughout embedding-model training. Text-only embeddings are therefore expected to remain unchanged from the matching Nemotron 3 Embed checkpoint, allowing existing text indexes to survive the upgrade, a welcome escape from re-embedding a corpus.
For the 1B model, distillation uses cosine-distance and mean-squared-error losses to align it with the 8B teacher, while the vision encoder and multimodal projection learn image retrieval.
Cross-encoder reranking
Rerank 8B jointly encodes each query-document pair, including page-image candidates. An MLP scoring head produces a scalar relevance logit; higher values indicate greater relevance, according to NVIDIA's architecture description.
ViDoRe v3 scores
NVIDIA reports these retrieval scores for combined image-and-text inputs on ViDoRe v3, measured as nDCG@10:
- Nemotron 3.5 Embed 8B: 61.5.
- Nemotron 3.5 Embed 1B: 58.8.
- Qwen3-VL-Embedding-8B: 57.0.
For the second-stage comparison, both rerankers score the same top 50 candidates retrieved by Embed 1B:
- Embed 1B alone: 58.82.
- With Qwen3-VL-Reranker-8B: 66.03, +7.21 points over retrieval alone.
- With Nemotron 3.5 Rerank 8B: 67.56, +8.74 points over retrieval alone and +1.53 points over Qwen's reranker.
On the separate ViDoRe v3.1 leaderboards, NVIDIA's launch post lists 61.17 for Embed 8B and 58.38 for Embed 1B, plus reranking scores of 60.49 for Nemotron versus 59.17 for Qwen. Those are separate results from the v3 experiments above.
Checkpoints and hosted access
The four retrieval checkpoints use OpenMDW-1.1:
- Nemotron 3.5 Embed 1B BF16.
- Nemotron 3.5 Embed 8B BF16.
- Nemotron 3.5 Embed 1B NVFP4, for Blackwell GPUs.
- Nemotron 3.5 Rerank 8B BF16.
The wider release includes Nemotron 3.5 Parse, a 631M-parameter model that extracts Markdown, HTML tables and structured blocks with page locations. Embed, Parse and Rerank are available on Baseten, according to its announcement.
Turbopuffer reports roughly 5% better recall@20 than the next-best model on its enterprise PDF search benchmark using Embed 8B. Its embedding changelog prices the 1B and 8B models at $0.02 and $0.05 per million tokens, respectively.
Runtime versions
The 1B model card documents a dependency split:
- Sentence Transformers examples:
sentence-transformers[image]>5.4withtransformers==5.20.0. - vLLM examples:
vllm==0.32.0, requiringtransformers>=5.16.1,<5.20.0, in a separate environment. - FlashAttention 2 caveat: Transformers 5.17.0, 5.18.0 and 5.19.0 can produce CUDA errors or incorrect outputs with image inputs in the Transformers and Sentence Transformers examples.