
Curious Refuge shows Seedance 2.5 performance transfer with depth maps
Curious Refuge’s tutorial turns greybox footage of an actress drinking coffee into a bar scene. Seedream sets the look, Depth Anywhere extracts depth guidance, and Seedance 2.5 generates the final video.
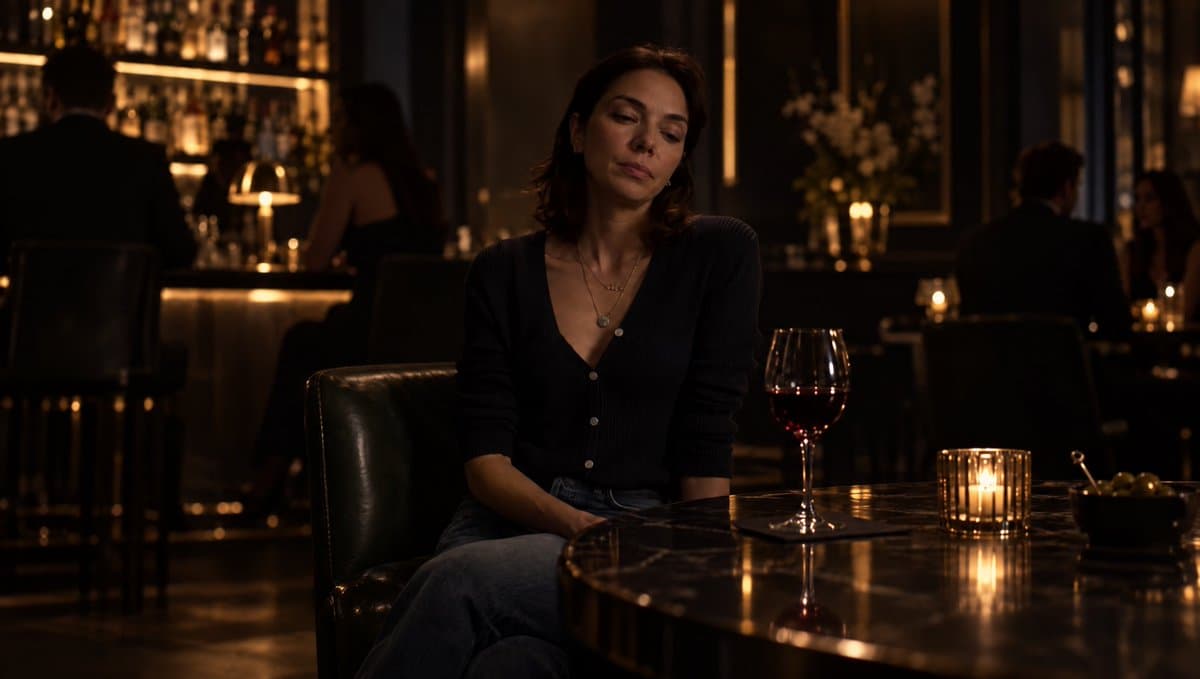
TL;DR
- A filmed coffee-sipping performance becomes a bar scene with a red dress and wine glass in CuriousRefuge's greybox test.
- Appearance and movement get separate references: the final Seedance 2.5 step combines an edited first frame, an outfit image and a depth video.
- The same approach also produces an Irish cliffside scene and a cave scene with an ancient scroll.
The full tutorial includes a failed take that brings the coffee cup back after it was replaced with wine. The depth service on fal costs $0.04 per second, while the cave workflow adds the original footage back in for facial detail.
Coffee into wine
Curious Refuge starts with an actress filmed in a simple greybox at Promise, then changes the setting, drink and wardrobe around her performance.
Seedream edits the starting frame using this prompt:
change the location/setting in @img1 to a classy upscale bar. Change the coffee cup to a glass of wine.
Don't change anything about the woman
The wardrobe change comes through a separate outfit reference. Seedance 2.5 then receives three inputs:
- Edited starting image: establishes the scene's look.
- Outfit reference: supplies the new wardrobe.
- Depth video: guides the motion.
The tutorial runs Seedance through Magnific and describes a 30-second clip limit, with output up to 1080p.
Depth Anything Video
Curious Refuge calls the depth tool “Depth Anywhere,” but the linked service is fal's Depth Anything Video. It estimates depth from the original footage with temporal consistency across frames, returning a video that becomes the motion reference.
The listed $0.04-per-second price makes a 10-second depth pass $0.40, before image editing or final video generation.
An Irish cliff
For the cliff shot, Curious Refuge used a second image as a color-grading, lighting and style reference when editing the starting frame.
The team prompted Seedance with explicit assignments for the edited still and motion video:
Use @Image 1 as the first frame
Use @Video 2 as the motion reference.
A woman is running when she suddenly stops at the edge of a cliff and looks down.
NO MUSIC. ONLY AMBIENT SFX
A screwdriver becomes a scroll
Another test turns an actress picking up a screwdriver into an archaeologist retrieving an ancient scroll inside a cave.
For this shot, the team supplied four references:
- Edited first frame: establishes the cave and scroll.
- Depth video: guides movement.
- Original greybox footage: supplies facial detail.
- Outfit image: specifies the character's clothing.
Failed takes and flat lighting
Curious Refuge kept the misses in its full tutorial, a welcome look at the limits of performance transfer:
- Props can revert: the first bar generation brought the coffee cup back.
- Gestures can drift: another take extended the actress's reach beyond the source performance.
- Costume details can disappear: the cave result omitted the hat from its outfit reference.
- Lighting can carry through: flat greybox lighting left some bar results looking flat. The presenter found Seedream changed the lighting more substantially than the GPT image model in that comparison.
- Depth is optional: the presenter says a depth reference can sometimes make results worse, and compares generations with and without it.
Nobody Dies on Mars
Separately, Curious Refuge shared Nobody Dies on Mars, Verena Puhm's short about a chef who loses his sense of taste on Mars and befriends an alien named Miso.
The film took second place and $100,000 at the 2026 Future Vision XPRIZE, according to the official results.