
Tinker cuts 128k and 256k context reinforcement learning costs by up to 70%
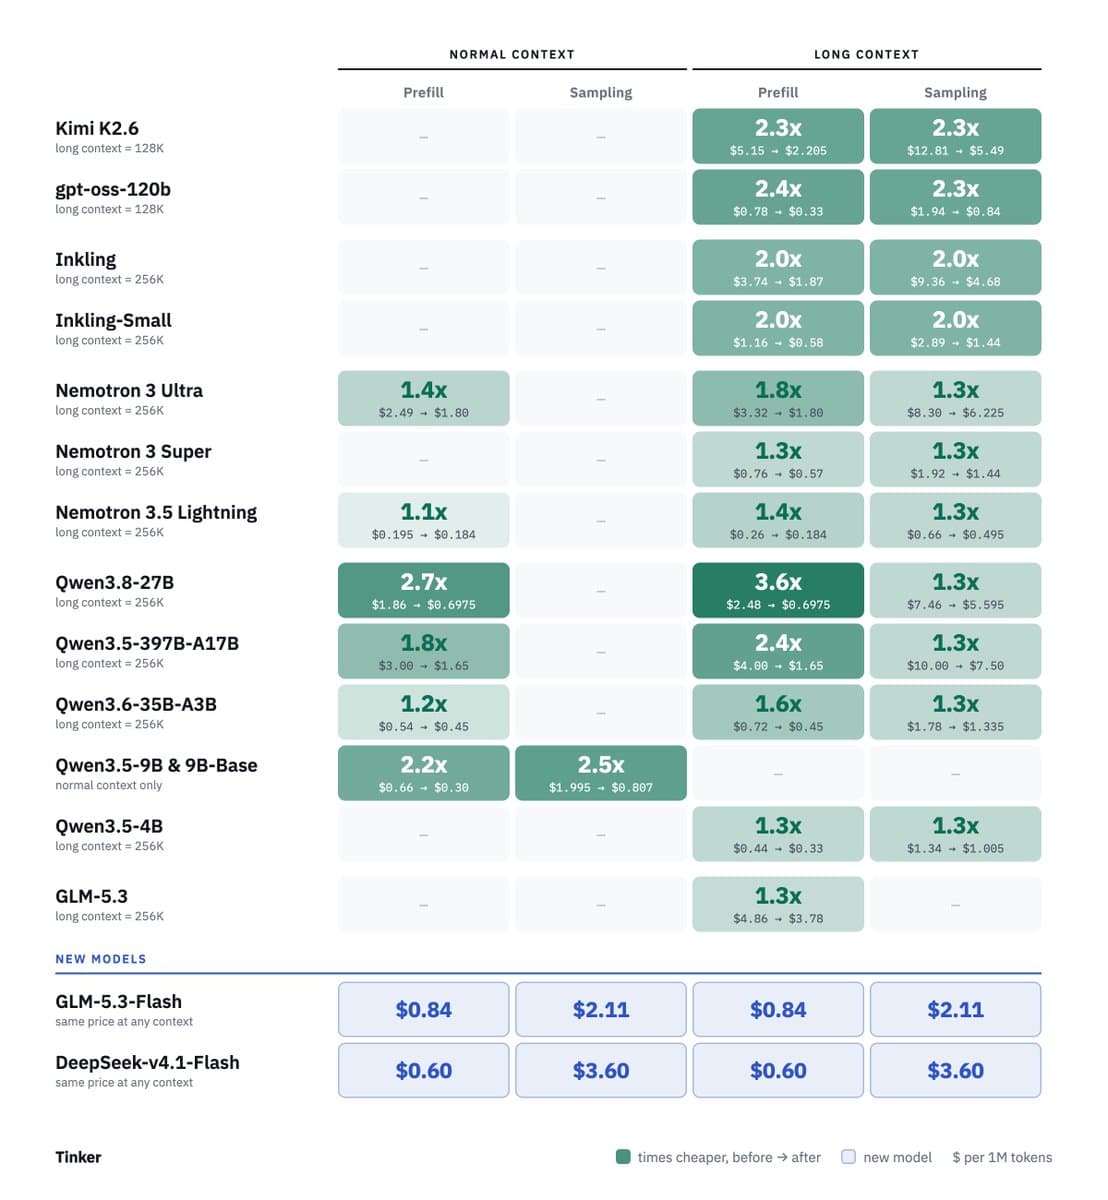
Tinker removed extra prefill charges for 128k and 256k contexts, cutting long-context reinforcement learning costs by up to 70%. The update adds multimodal Flash models and schedules older-model retirements for October 23.
TL;DR
- Long-context price cuts reach 70%, according to Tinker's announcement, following efficiency improvements for RL workloads.
- The 128k and 256k prefill surcharge is gone, as Tinker detailed in its pricing follow-up.
- GLM-5.3-Flash and DeepSeek-v4.1-Flash are live with native image inputs, according to Tinker's model update.
- Three older models retire October 23, with same-family replacements listed in the retirement announcement.
Forward-only passes made through a training client still incur the training rate, according to Tinker's billing definitions. Its JSON pricing feed exposes cached-prefill prices and temporary-discount fields alongside the main rates.
128k and 256k prefill
Tinker says growing long-context RL workloads drove the efficiency improvements behind the cuts.
The update removes the extra prefill charge for 128k and 256k contexts and includes more targeted reductions:
- Kimi K2.6, gpt-oss-120b and Inkling: an effective prefill discount of over 2x, according to Tinker's pricing follow-up.
- Seven Qwen and Nemotron models: further prefill discounts.
- Qwen3.5-9B and Qwen3.5-9B-Base: lower sampling prices.
Rollout billing
Agent rollouts repeatedly process a growing history of tool outputs, files and earlier turns, as omarsar0 described in a follow-up on agentic RL. The disappearing prefill surcharge is the prize for those multi-turn runs.
Tinker defines three separate token charges:
- Prefill: processing input or prompt tokens during sampling.
- Sample: generating output tokens.
- Train: forward and backward passes for gradient computation.
Prompt-cache hits qualify for an 80% prefill discount under the documented pricing rules. Total RL spend combines those meters; token counts and cache hits determine how much of a run benefits from the lower rates.
Longer prompts still contribute more billable input tokens at the new rate. Evaluations that generate responses from long inputs also incur prefill charges, so the reductions extend beyond rollout collection.
Flash models and Qwen context
Both new Flash models accept images natively and use efficient attention architectures, according to Tinker.
Flash models
- GLM-5.3-Flash: 4-5 times cheaper on Tinker than GLM-5.3.
- DeepSeek-v4.1-Flash: joins the lineup for cost-efficient long-context work.
New long-context options
- Qwen3.5-4B
- Qwen3.6-35B-A3B
Tinker's announcement does not specify the context lengths or individual rates for those two new Qwen options.
October 23 retirements
Tinker says it is retiring three models to keep throughput high. Its announced replacements are:
- Qwen3.6-27B → Qwen3.8-27B
- Nemotron-3-Nano-30B-A3B → Nemotron 3.5 Lightning
- DeepSeek-v3.1 → DeepSeek-v4.1-Flash
The deprecation table lists September 2 for Qwen3.6-27B, while this announcement sets October 23. Under Tinker's retirement rules, retired models become unavailable for both training and inference.