
ARC Prize reports lower matched-effort scores for GPT-6 Sol than GPT-5.6 Sol
ARC Prize reports lower ARC-AGI-1 and ARC-AGI-2 scores for GPT-6 Sol than GPT-5.6 Sol at matched effort. Lower prices and fewer reasoning tokens cut per-task costs by over 70%.
TL;DR
- GPT-6 Sol scored 78.1% on ARC-AGI-2 at xhigh effort, down from GPT-5.6 Sol’s 90.0%, according to ARC Prize’s comparison.
- ARC-AGI-1 fell from 97.5% to 92.7% at xhigh, while cost per task dropped 73% across matched effort levels, per ARC Prize’s follow-up.
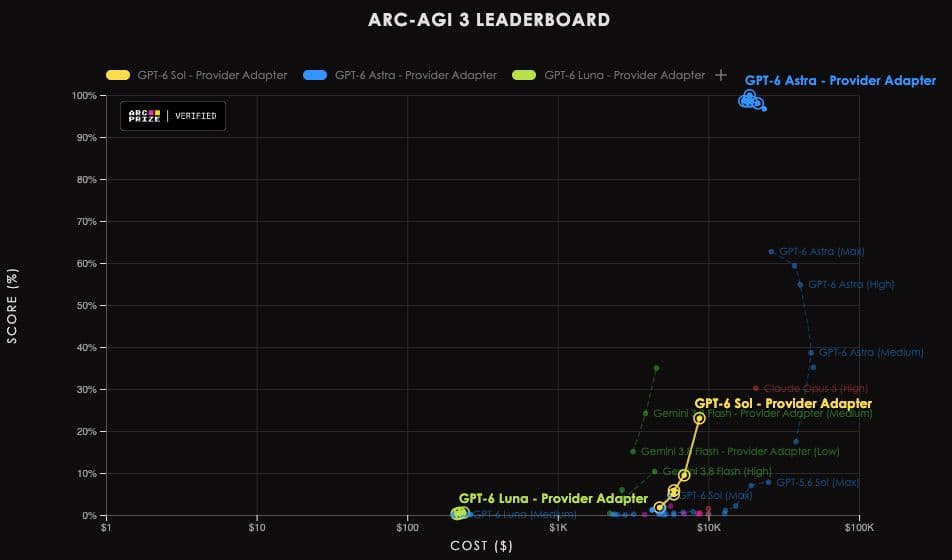
- On interactive ARC-AGI-3, the harness changed Sol’s max-effort score from 4.6% to 23.0%, as ARC Prize’s results post reports.
The per-game results show Sol scoring 0.0% on TR87 with the standard harness and 80.3% with the provider adapter at max effort. OpenAI’s launch post measures its 50% API price cut against GPT-5.6 Sol’s promotional rates.
Matched-effort scores
ARC Prize’s GPT-5.6 Sol and GPT-6 Sol result tables show declines at both xhigh and max reasoning:
- ARC-AGI-2, xhigh: 90.0% → 78.1%, −11.9 points, as ARC Prize’s comparison notes.
- ARC-AGI-1, xhigh: 97.5% → 92.7%, −4.8 points, per ARC Prize’s follow-up.
- ARC-AGI-2, max: 92.5% → 89.6%, −2.9 points, in the linked result tables.
- ARC-AGI-1, max: 96.5% → 95.5%, −1.0 point, in the same tables.
Cost per task
OpenAI cut Sol’s standard input and output prices from $4/$20 to $2/$10 per million tokens relative to GPT-5.6’s promotional prices, according to its launch announcement. ARC Prize reports the resulting evaluation costs separately from accuracy:
- ARC-AGI-2: 71% cheaper per task than GPT-5.6 Sol; Sol used 19% fewer reasoning tokens, according to ARC Prize’s cost comparison.
- ARC-AGI-1: 73% cheaper per task across matched reasoning levels, per ARC Prize’s follow-up.
- At max effort: $0.44 per ARC-AGI-2 task and $0.14 per ARC-AGI-1 task, from ARC Prize’s results post.
ARC-AGI-3 harnesses
At max reasoning, ARC Prize’s results post gives Sol 4.6% under the standard harness for a $5.6K evaluation, versus 23.0% under the provider adapter for $8.7K. That is an 18.4-point score difference for the same model at the same effort level.
The testing policy describes what changed:
- Standard: A provider-neutral interface that carries forward notes the model chooses to keep.
- Provider adapter: Provider-designed context management that can preserve opaque reasoning state between requests and compact long conversations.
Public runs and verified scores
The verified testing policy says ARC Prize uses a single run per evaluation rather than averaging runs. Its ARC-AGI-1 and ARC-AGI-2 verified scores use a semi-private set; public-task outputs, costs, durations and task scores are published separately. ARC Prize links its open-source benchmarking runner for reproducing public results.