
Fresh stories
Briefs forNovember 16
Top storiesthis week
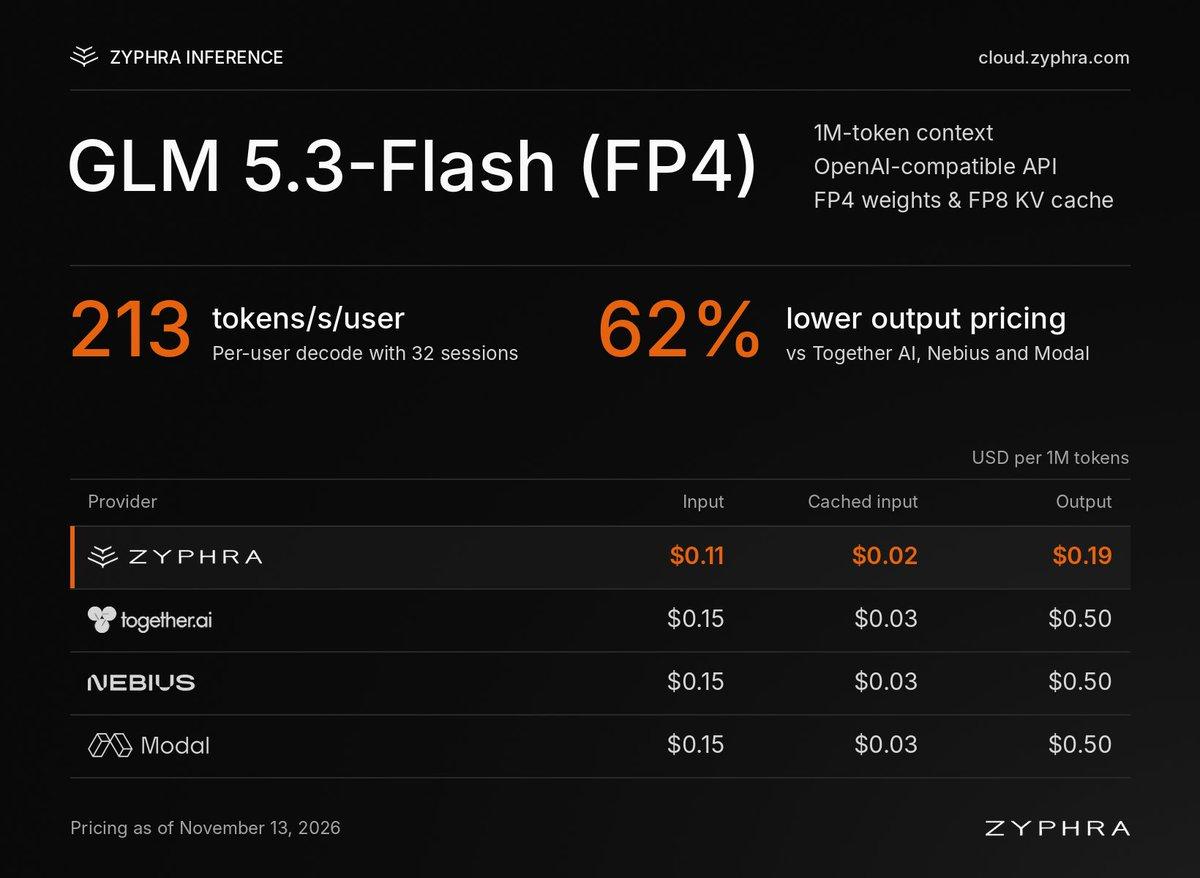
Zyphra prices GLM-5.3-Flash FP4 inference 25% below FP8
Zyphra prices FP4 inference on MI300X GPUs 25% below its FP8 offering. AgentX tests report 9.5× faster p90 generation than stock SGLang, with about 95% of input tokens served from cache.
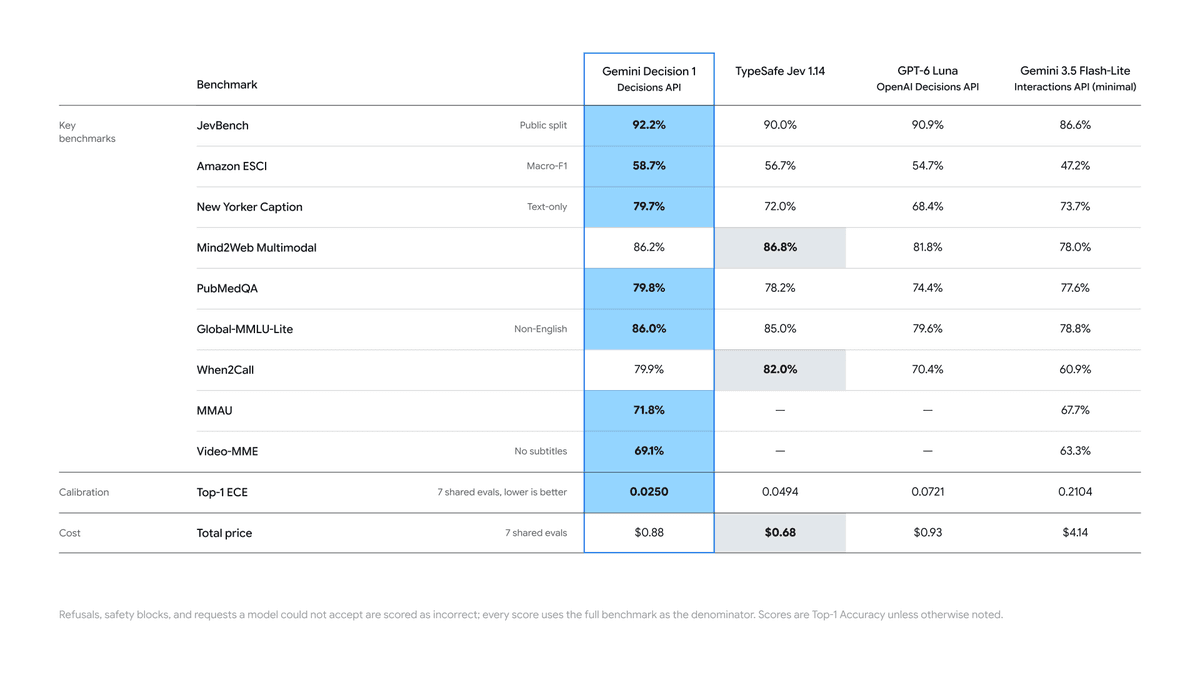
dspy-wsp adds weight-space optimization to DSPy’s optimizer interface
dspy-wsp exposes weight-space optimization through DSPy’s optimizer interface, supporting MLX, PyTorch and vLLM. Its authors report improving every tested decision model with roughly $5–10 of Astra usage.
Inkling 2 Small uses four-bit training, Thinking Machines reports 8% and 20% savings
Thinking Machines says Inkling 2 Small uses four-bit forward passes throughout pretraining and reinforcement learning. It reports training-time savings of 8% and 20%, respectively, without a separate checkpoint quantization step.
llama.cpp ships its first stable major release
llama.cpp and ggml have reached their first major release. The team commits to broad platform support, while Cohere separately announced runtime support for its North Micro Vision architecture.
LMSYS reports Vera CPUs cut agentic RL episode time by 11%
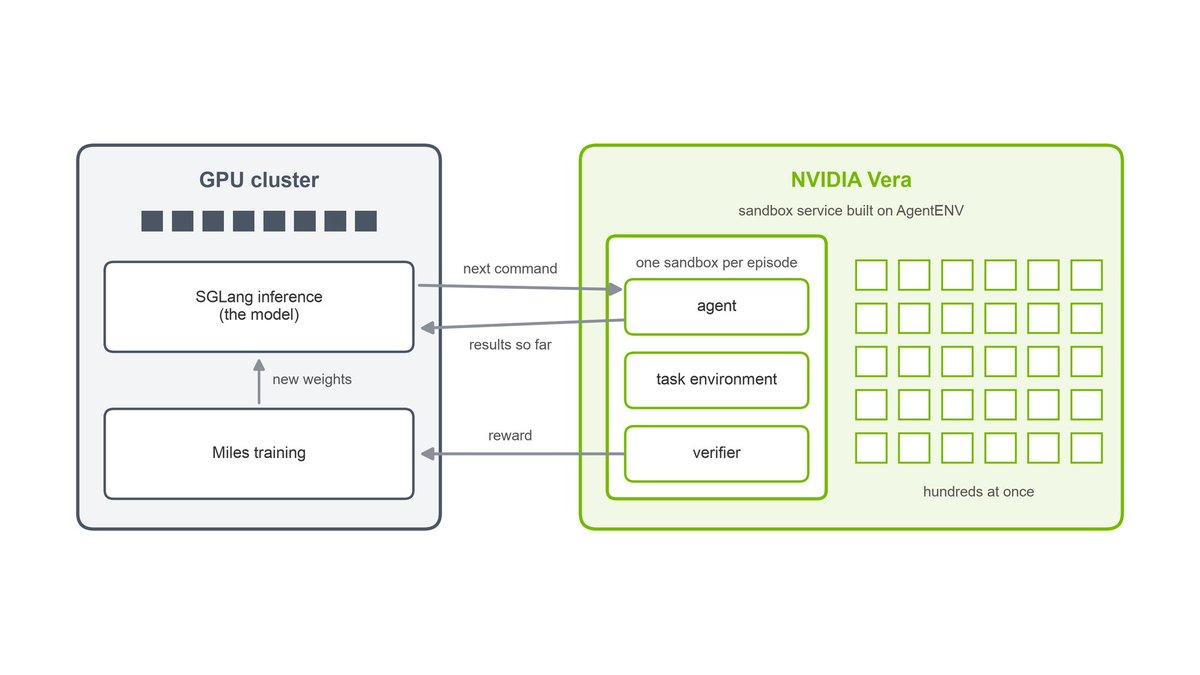
LMSYS reports that Vera CPU sandboxes reduced average agentic RL episode time by 11% in Miles tests under load. Command latency rose 5–22% as concurrency increased from one to 176 sandboxes per socket.
Daily AI Digest
Get the best stories delivered
to your inbox