
Tools for this
Browse all ->A unified interface for LLMs.

A high-throughput and memory-efficient inference and serving engine for LLMs.

A fast serving framework for large language models and vision language models.

Get up and running with large language models.
The AI community building the future.

The fastest way to build with Gemini.

Bring Grok to your computer.

LLM inference in C/C++
Fresh stories
Modal details per-second sandbox pricing with a requested minimum
Modal bills sandbox resources each second, subject to a requested minimum, while bursts use spare host capacity. Modal says typical sandboxes spend over half their lifetime below 6% of peak CPU use.
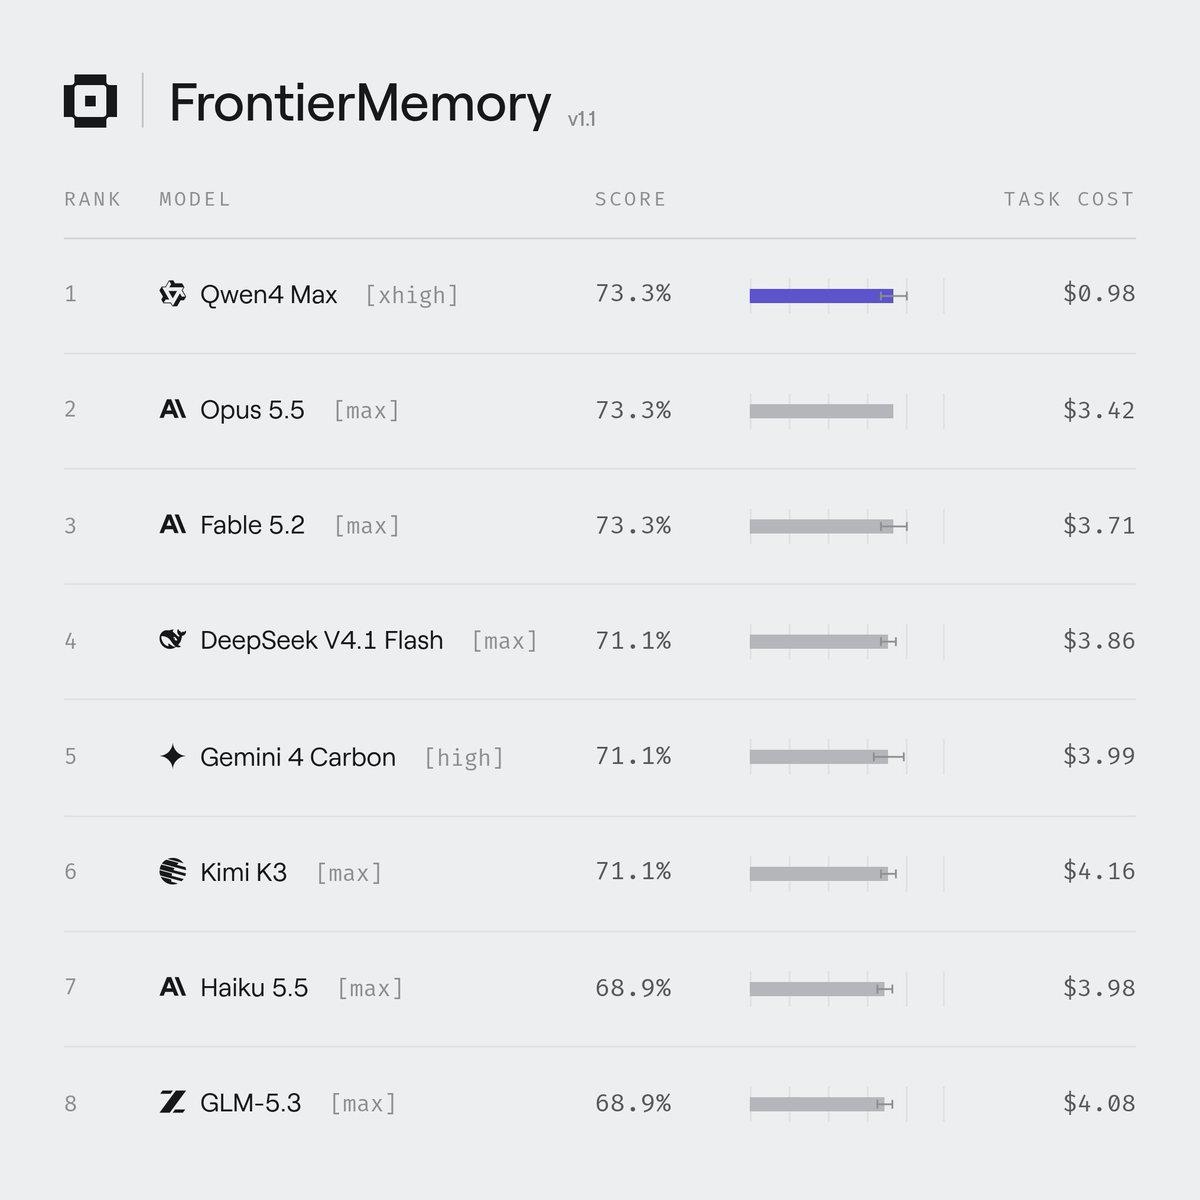
Hugging Face adds OpenRouter routing for 160 chat models
Hugging Face integrates OpenRouter for access to 160 chat models using existing tokens and code. Routing selects providers by price, speed or reliability, with failover within a single API call.
Modal details per-second sandbox pricing with a requested minimum
Modal bills sandbox resources each second, subject to a requested minimum, while bursts use spare host capacity. Modal says typical sandboxes spend over half their lifetime below 6% of peak CPU use.
OpenAI signs assessment agreements with four outside research groups
OpenAI has assessment agreements with METR, Apollo, Transluce and Goodfire. METR's scope is limited to one reinforcement-learning run, while access restrictions and publication commitments vary across assessors.
Briefs forNovember 16
Top storiesthis week
EmbeddingGemma 2 maps text, code, images, video and audio into one embedding space
A technical breakdown describes EmbeddingGemma 2’s shared embeddings for text, code, images, video and audio. It details staged distillation from Gemini Embedding 2, Matryoshka dimensions and int4 training.
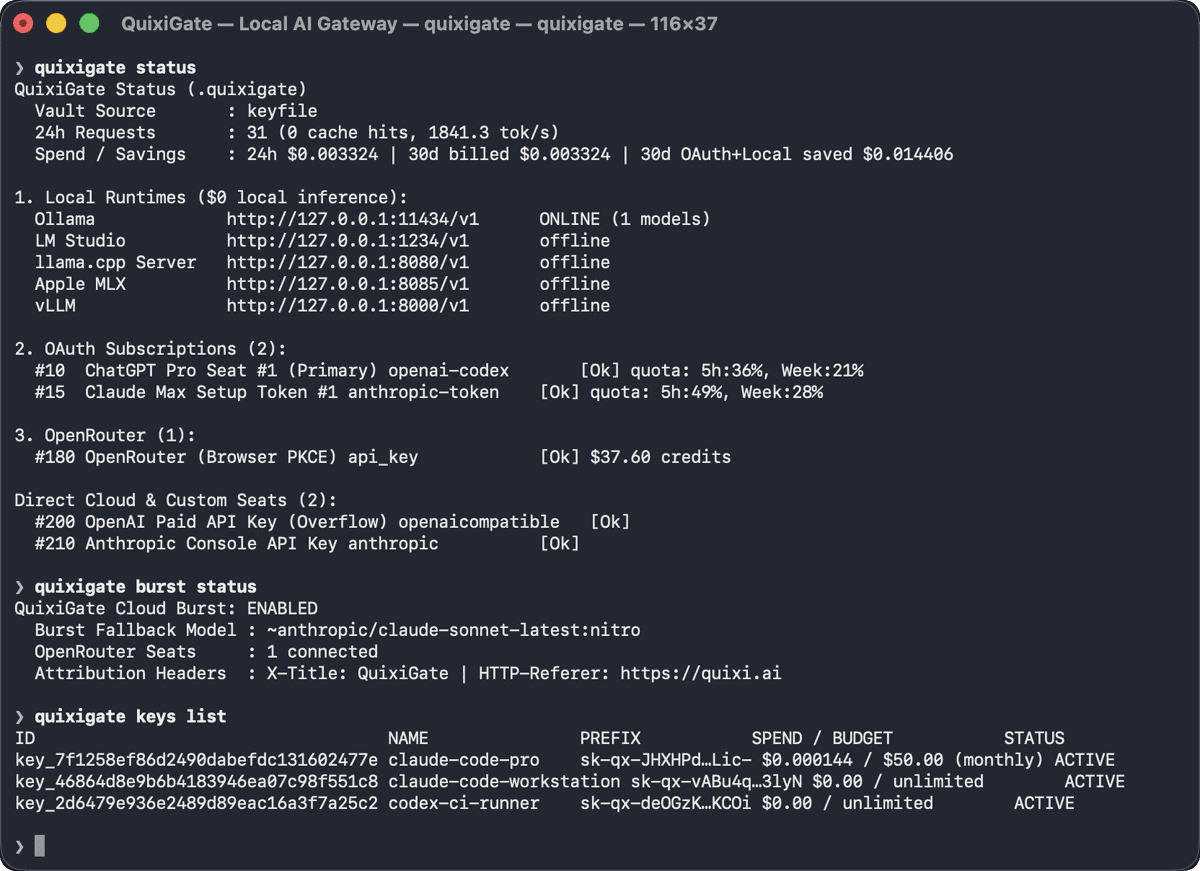
QuixiAI releases MIT-licensed QuixiGate Rust gateway
QuixiGate ships as a cross-platform Rust binary for routing requests to cloud and local models. It supports OAuth subscriptions, telemetry integrations and configurable fallback when usage limits are reached.
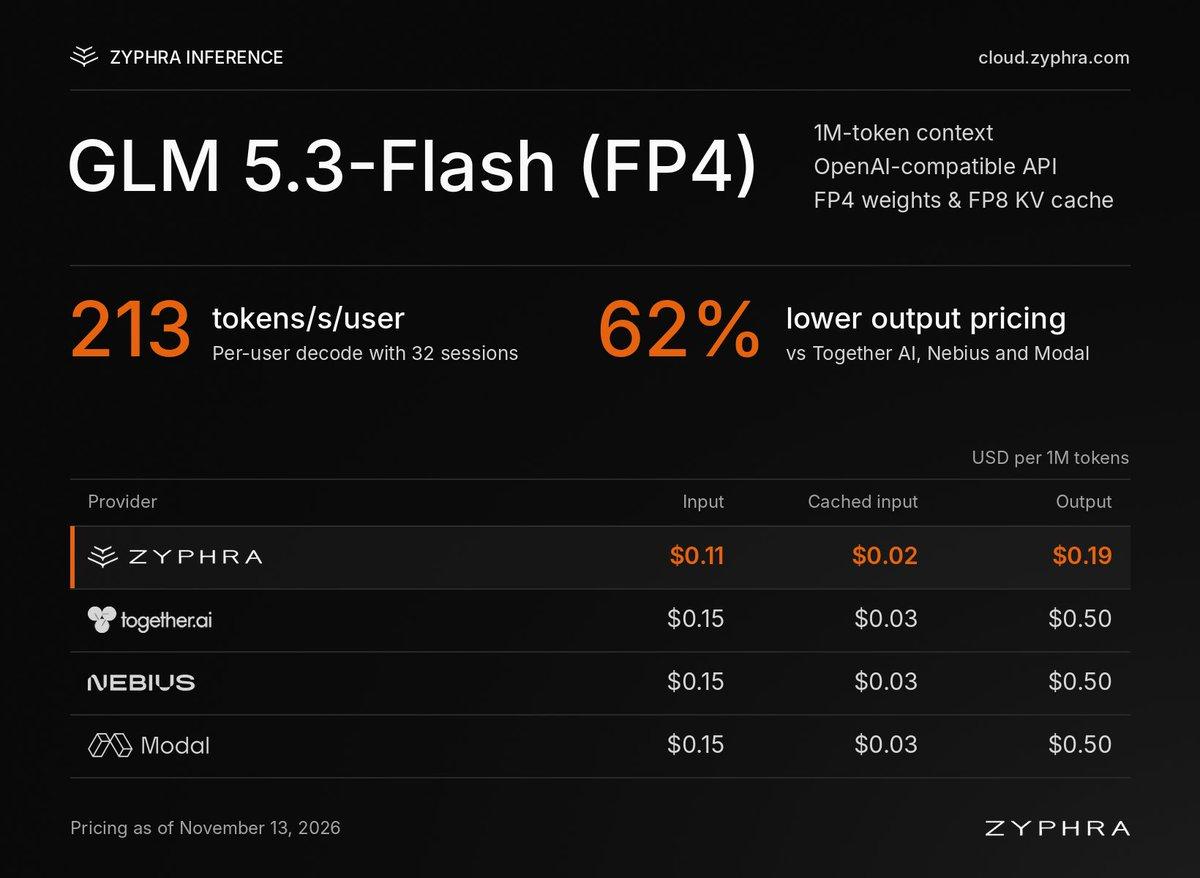
Zyphra prices GLM-5.3-Flash FP4 inference 25% below FP8
Zyphra prices FP4 inference on MI300X GPUs 25% below its FP8 offering. AgentX tests report 9.5× faster p90 generation than stock SGLang, with about 95% of input tokens served from cache.
dspy-wsp adds weight-space optimization to DSPy’s optimizer interface
dspy-wsp exposes weight-space optimization through DSPy’s optimizer interface, supporting MLX, PyTorch and vLLM. Its authors report improving every tested decision model with roughly $5–10 of Astra usage.
Inkling 2 Small uses four-bit training, Thinking Machines reports 8% and 20% savings
Thinking Machines says Inkling 2 Small uses four-bit forward passes throughout pretraining and reinforcement learning. It reports training-time savings of 8% and 20%, respectively, without a separate checkpoint quantization step.
Daily AI Digest
Get the best stories delivered
to your inbox