
Dan Shipper reports Muse Wonder scored 52% on a codebase rewrite test
Dan Shipper reports Muse Wonder Standard scored 52% versus Sol's 71% after he corrected a faulty test. He tested Standard because Full was unavailable through the API, and other early coding tests produced mixed results.
TL;DR
- Muse Wonder Standard scored 52% against GPT-6.1 Sol’s 71% on a codebase rewrite, a 19-point gap, in the corrected result.
- Full was unavailable through the API when Shipper tested, he clarified; theo’s top-tier assessment applied specifically to Full.
- Early coding results were mixed: a lava-lamp attempt produced a red cylinder, while Full found an existing bug-fix PR instead of writing another patch.
The live scoreboard now shows 48% for Muse, while Shipper’s posted screenshot records 52%. An Arena-shared test video uses “Max” to mean maximum reasoning on the API model, not Wonder Full.
Codebase rewrite
Dan Shipper, publisher of the Senior Engineer Benchmark, tested models on rebuilding a “vibe-coded” codebase from scratch. He withdrew an earlier run after finding a problem, then confirmed the rerun was back up.
The published methodology specifies:
- Programmatic code checks and model checks judged by Claude.
- Each case’s latest public run determines its score; task scores average across cases.
- The displayed comparison contains six models and one task. Muse and Sol used Codex CLI at high effort; the Claude models used Claude Code at high effort.
Muse’s current live score is 48%, versus the screenshot’s 52%; Sol remains at 71%. The page does not explain the change in Muse’s score.
Standard, Full and Max
Shipper identified his tested model as Standard in a follow-up. Meta’s developer page makes Wonder available through the Model API and Muse Code, while Full is available to Muse Code subscribers.
The naming did these comparisons no favors. After putting Muse alongside Opus 5.5 in his original ranking, theo clarified that he meant Full and considered the API version significantly worse.
Wonder “Max” in the video shared by arena means maximum reasoning on Wonder. The presenter explicitly says Full was not tested, despite the similar naming.
DeepSWE and unfamiliar tasks
- DeepSWE: Cline announced a Muse Wonder lead. Meta specifically credits Full with topping DeepSWE and SWE-Marathon in independent third-party runs.
- Generalization: Meta reports an unfamiliar-task experiment in which Full performed better than the Spark 1.3 trend predicted from its scores on tasks targeted during post-training.
Full in coding agents
Full’s most interesting bug-fix result was its decision to reuse someone else’s work. In theo’s comparison, it found an existing small PR and suggested merging it.
GPT-6.1 Sol’s proposed fix would not have worked, theo confirmed afterward. Other hands-on reports exposed different strengths:
- Compiler work: QuixiAI reported faster work than Claude Code with
muse-wonder-full-1.0at high effort, while rating its quality below Fable and Opus 5.5. - Queued requests: Muse Code retained roughly 20 requests delivered incrementally during work, according to QuixiAI’s follow-up; Claude Code reportedly lost track of some.
- Instruction files: Global agent instructions strongly affected Muse’s writing in theo’s usual T3 Code workflow, he reported.
Lava lamps, SVGs and UI
A BridgeBench lava-lamp attempt prompted bridgemindai to accuse Wonder of being “benchmaxxed”: the reported result was a red cylinder without glass or lava.
The author subsequently called it “a data point to consider” in a reply and shared a Grok 4.7 comparison.
Full also drew criticism in scaling01’s SVG comparison. The tester disclosed free Meta preview access, self-funded Opus access, and judged Full’s style gimmicky and overloaded with objects.
Despite his positive coding assessment, theo separately criticized Full’s UI output as a throwback to 2024 Lovable websites.
Writing tasks
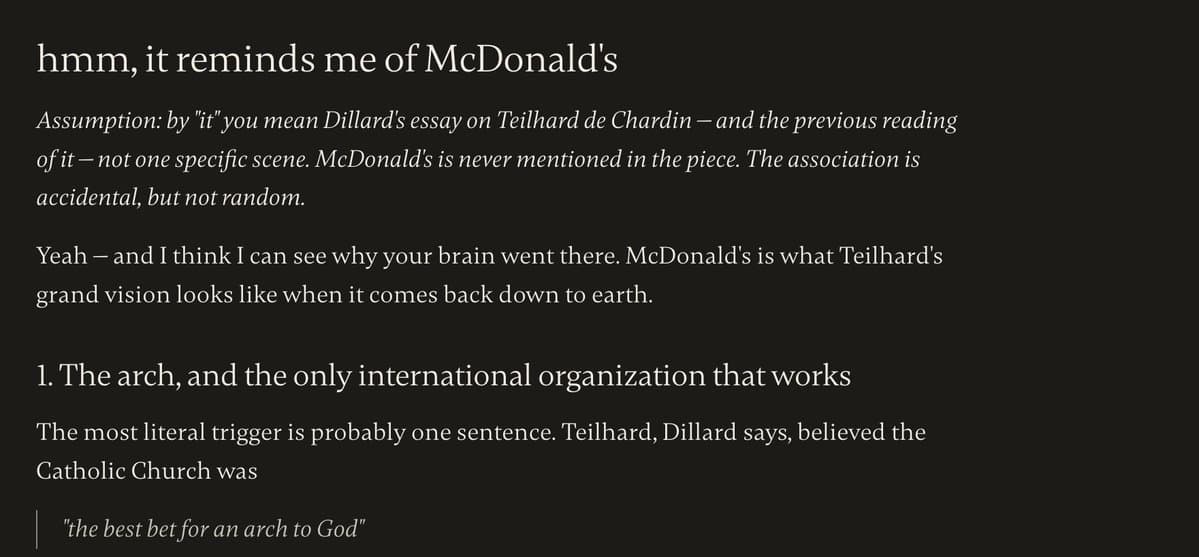
Wonder accepted a suggested connection between Annie Dillard’s For the Time Being and McDonald’s in Shipper’s literary-analysis canary test.
His other writing results varied by task:
- Metaphor revision: Shipper reported a failed revision attempt.
- Literary reading: A War and Peace scene analysis topped one of his reading tasks, he added in the same thread.
- Newsfeed cards: Output for an internal Every newsfeed looked decent to him.
- Job descriptions: Muse topped his job-description task; he praised its thoroughness and connection between the role and the company’s purpose in a follow-up.